Next.js, FastAPI, Supabase and LangGraph: An AI SaaS Stack and 8-Week Build Plan
Keep the interface and the AI engine in separate services, and make sure tenant isolation still works from the backend. This post sets out the stack, the security mistake that undoes it, and an eight-week build sequence.
Many teams start by calling a model provider's SDK straight from their Next.js API routes. That works fine for a weekend demo. Then a real user starts a multi-step agent task. The serverless function hits its time limit and the user watches a spinner. Often nobody gets an error.
That isn't a bug you can patch. The architecture is wrong, and fixing it later often requires a significant rewrite.
The fix is to give each job its own tool. If you are adding AI to a product you already run, the retrofit post covers the sidecar version of this design. For a new product, the split looks like this. Next.js runs the interface. FastAPI runs the long Python AI work. Supabase holds the data, the logins and the vectors. LangGraph controls what the agent is allowed to do.
Next.js and FastAPI live apart
Next.js is the right choice for the interface. It handles routing, client state, dashboards and generative UI components that render from model output. It is the wrong place for the AI engine.
There are two reasons, and one of them is about money.
The first is the ecosystem. JavaScript AI tooling has matured, but evaluation frameworks, document parsers, data processing libraries and local inference bindings still usually ship for Python first. If your engine runs in Node.js, your engineers end up writing and maintaining bridges to those libraries. That time doesn't go into your product.
The second is runtime limits. Serverless platforms cap how long a function can run. On Vercel, for example, a function runs for 300 seconds by default and for at most 800 seconds on Pro and Enterprise plans. Vercel's function duration docs list the limits per plan. An agent that searches, reads a long PDF and drafts a report can go past that limit. When it does, the task dies halfway through.
So the boundary is strict. Next.js serves the user. FastAPI runs the AI on a persistent container, on platforms such as Railway, Render or Modal. Next.js makes an authenticated request to FastAPI. FastAPI runs the LangGraph workflow and streams progress back using Server-Sent Events (SSE), a simple one-way stream from server to browser.
Streaming keeps the user engaged with messages like "Reading document..." and "Checking clauses...". It also needs one more piece. If the user closes the tab, the stream ends, and the task shouldn't end with it. Run the graph as a background job and save its progress. A returning user then reconnects to the same run instead of paying for a new one.
Supabase: one database, and the security trap inside it
An AI SaaS product needs relational data, user logins, vector search for retrieval and strict separation between customers. Running a separate service for each one adds monthly bills and integration bugs. Supabase puts all four in one PostgreSQL database.
The pgvector extension lets document chunks and their embeddings sit next to your accounts and billing tables. You have no second database to keep in sync. For a first release, that simplicity saves real weeks.
Tenant isolation is the requirement that decides enterprise deals. Customer A's agent must never retrieve Customer B's contracts. One leak can breach a contract. It can also create legal obligations, depending on what the data is and where it sits. Examples include HIPAA in the US and the PDPL in Saudi Arabia.
PostgreSQL's Row Level Security (RLS) is the standard tool for this. You write a policy that says a user may only read rows that belong to their organisation. Then the database enforces that rule on every query. Supabase documents RLS as granular authorization rules that run inside the database itself.
This is the trap. RLS only protects you if the query runs as the user. Supabase gives you a service-role key that bypasses RLS completely. Backend developers often put that key in FastAPI because it just works. When that happens, every vector search from your AI engine can read every tenant's data. If an engineer forgets a filter, the database won't catch it.
You have two correct options.
- ▸Forward the user's identity. Next.js passes the signed-in user's Supabase access token (a JWT, the signed login token) to FastAPI. FastAPI then queries Supabase with the public anon key plus that token, so RLS applies as intended.
- ▸Enforce tenant filters in code. If the backend must use the service-role key, for example in background jobs, every query requires a tenant ID. That rule lives in one shared data-access layer, and tests prove it can't be skipped.
The strongest designs use both. Watch one more detail too. Vector search in Supabase usually runs through a Postgres function. If that function is declared SECURITY DEFINER, it runs with its owner's privileges and can sidestep the caller's policies. Declare it SECURITY INVOKER unless you have a specific reason not to.
pgvector with an HNSW index (a fast approximate-search index) handles a first release and well beyond. Move vectors to a dedicated engine like Qdrant when you measure a problem, such as filtered query latency or index memory pressure. Don't move because of an assumed threshold. Our local RAG on 6GB VRAM post covers Qdrant deployments.
LangGraph: the model reasons, your code decides
A familiar failure is the agent left to loop on its own. It thinks, picks a tool, acts, and repeats until it decides it's finished. On edge cases it can loop, wander or keep spending API credit with nothing to show for it. That is a budget risk, not just an engineering annoyance.
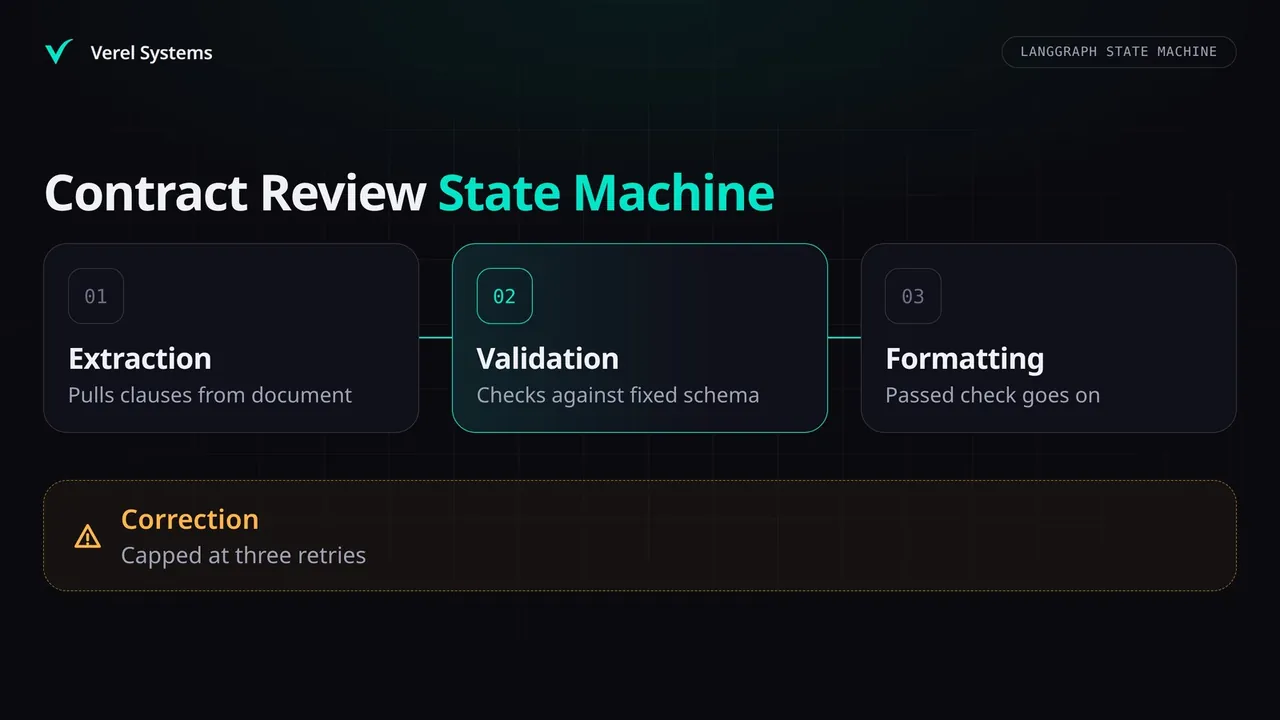
LangGraph models the workflow as a state machine. You define the steps (nodes) and the rules for moving between them (edges). For a contract review product, that looks like this:
- ▸An extraction step pulls clauses from the document.
- ▸A validation step checks them against a fixed schema.
- ▸A failed check goes to a correction step, capped at three retries.
- ▸A passed check goes on to formatting.
The model no longer controls the flow. It reasons inside the boundaries you set. Retry caps and step limits put a ceiling on cost for each run. Our LangGraph production patterns post covers these guards in more depth.
LangGraph also ships a Postgres checkpointer, published as the langgraph-checkpoint-postgres package. It saves the graph's state to your Supabase database after every step, and that's what makes human approval practical. The agent drafts an email and pauses. It waits hours or days for a user to click "Approve" in the dashboard, then resumes exactly where it stopped. Where those approval screens belong, and what the reviewer has to see, is its own post. The same checkpoints let a disconnected user rejoin a running task.
The eight-week sequence
Order matters more than speed. You can't build the interface until the API contracts are stable. You shouldn't build agents until the data model is secure. The table is the sequence we work to, phase by phase, with the thing you hold at the end of each one.
| Phase | Weeks | Engineering focus | What you have at the end |
|---|---|---|---|
| Foundation | 1 to 2 | Supabase schema, RLS policies, auth. JWT forwarding from Next.js to FastAPI. Containers deployed. | A deployed, empty product: sign-up works, and an automated test fails if the backend can read another tenant's rows. |
| AI engine | 3 to 4 | LangGraph state machine, tool integrations, document ingestion and retrieval in FastAPI. | The core workflow runs end to end from an API call, with capped retries, saved state and a first test set of real inputs. |
| Interface | 5 to 6 | Next.js dashboard, SSE streaming, approval screens, reconnect to running tasks. | A usable product: users watch the agent work, approve its actions, and a closed tab does not lose a run. |
| Production | 7 to 8 | Langfuse tracing, cost per tenant, load tests on concurrent runs, edge-case fixes. | A launchable system with traces of every run, a cost figure per tenant and a load test you can show a buyer. |
Eight weeks fits a focused first product with one core workflow. Add more integrations, a second language or on-prem hosting, and the plan grows. A fixed scope agreed in writing shows you that before you commit.
What it costs to run
Separate fixed hosting from model usage. They behave differently as you grow.
Fixed hosting stays small at launch. At list prices when this was written, Supabase Pro starts at $25 a month plus usage, and Vercel Pro starts at $20 a month. A small always-on FastAPI container usually costs tens of dollars a month on usage-based platforms. Check current pricing before you budget.
Model usage drives the bill. Use your own numbers in this formula.
</>View technical implementation · عرض التفاصيل التقنية
Monthly inference cost = tasks per month × steps per task
                         × (input tokens × input price + output tokens × output price) ÷ 1,000,000
Prices are per million tokens. Whatever the formula gives you, treat it as a floor. Real bills run higher. Retrieved context grows, failed steps retry, evaluation runs consume tokens, and some steps need a larger model. The small fast tiers of the Claude, GPT and Gemini families handle routing and extraction well. Use larger models only on the steps that need them. The retrofit post carries a worked example of this formula with the arithmetic shown.
The cost number that matters is cost per tenant, measured from the first week of real traffic. Langfuse in the FastAPI layer records every prompt, tool call, latency and token count. Without it, you can't price your plans with any confidence.
Frequently Asked Questions
Why not run everything in Node.js to keep the team smaller? Because the AI tooling you need most arrives in Python first. That includes evaluation, document parsing and data processing. Keeping a separate FastAPI service costs far less than building and maintaining bridges to those libraries. One small Python service is still a small team.
Does Supabase RLS protect our data if the AI backend queries the database? Only if the backend queries as the user. The service-role key bypasses RLS completely. Forward the user's JWT to FastAPI and query with the anon key. Or, where the service key is unavoidable, require a tenant ID in a shared data-access layer and test it.
How do we handle agent tasks that take several minutes? Run the graph as a background job on a persistent container. Checkpoint each step to Postgres. Stream progress over SSE, with periodic heartbeat messages so proxies don't drop an idle connection. If the user disconnects, they reconnect to the same run using its ID.
→ How to Add an AI Feature to Your SaaS Without Rebuilding the Product → Buying AI Engineering as a Non-Technical Founder: Three Questions and One Cost Formula → Pricing an AI SaaS Product: Seat-Based, Metered, or Hybrid CreditsIf you already have a prototype, run one check this week. Find which Supabase key your AI backend uses. If it's the service-role key and no tenant filter is enforced in code, fix that before you onboard another customer.