Human-in-the-Loop AI Agents: Where to Put the Approval Gate and How to Build It
An agent that pauses for approval, accepts edits, and escalates when unsure is the version that reaches production. Here is where to place each checkpoint, what it costs, and how the pause actually works.
Picture an AI agent that drafts a commercial lease and emails it straight to the tenant with nobody checking it. That isn't automation. It's a liability that can send email.
Language models make mistakes at some rate, and no amount of prompt writing gets that rate to zero. Teams that try usually end up with a growing pile of "never do X" instructions. The pile gets harder to maintain and still lets the occasional error through. Swapping one model family for another moves the error rate around. It doesn't remove it.
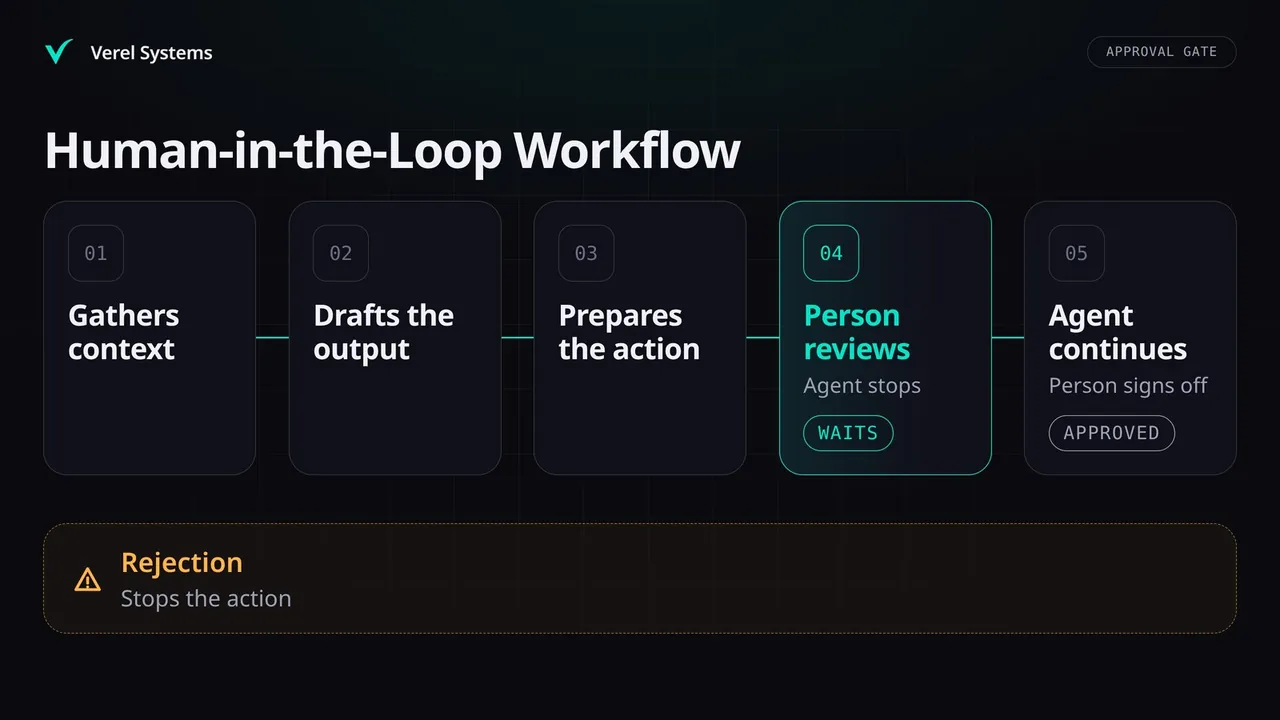
Production systems accept the mistakes and design around them. The agent does the slow part: it gathers context, drafts the output, and prepares the action. Then it stops. A person reviews the work, and the agent only continues once that person signs off. People call this human-in-the-loop, or HITL. It's the most dependable way we know to get a high-stakes agent out of pilot and into daily use.
Three ways a human enters the loop
"Human-in-the-loop" often gets used to mean "there's a chat window." In a production system it means something narrower. Specific points in the agent's workflow are coded to pause and wait for a human. In practice there are three kinds.
Approval gate. The agent finishes a piece of work and pauses before any action that leaves the building or can't be undone. Examples include sending a proposal, issuing a refund, or writing to the ERP. A reviewer approves or rejects. Approval runs the action, and rejection stops it.
Edit and resume. Often the draft is mostly right. Rejecting it wastes work that's already been paid for. So the reviewer fixes the wrong fields and sends the corrected version back. The agent carries on with the human's version as its new source of truth.
Escalation. Sometimes the agent lacks the authority or the facts to decide, and it shouldn't guess. Picture a refund request five days past the 30-day window from a customer who cites a known product defect. The agent sends a pointed question to a person. The person's answer becomes an instruction, and the agent completes the case. An output check that cannot tell whether a draft is safe uses the same route. Its verdict is escalate, and the draft waits for a person.
Each pattern adds delay and costs reviewer time, so put them only where an error would be expensive. This table is how we decide:
| What the agent is about to do | Can it be reversed? | Who sees it? | Pattern |
|---|---|---|---|
| Read, search, summarize for internal use | Yes | Internal staff | No checkpoint. Log it. |
| Draft an internal note or ticket update | Yes | Internal staff | No checkpoint. Spot-check a sample. |
| Send anything to a customer, tenant, or patient | No | External | Approval gate, with editing allowed |
| Move money, change a contract term, commit inventory | Rarely | External | Approval gate with required field checks |
| Act on a case that falls outside written policy | Depends | Either | Escalation with a specific question |
| Delete or overwrite records | No | Either | Approval gate, plus a separate human trigger |
What you're really deciding is reversibility and audience. An internal draft that's wrong costs a few minutes. A wrong email to a client costs a relationship. Inbound work has a gate in the same place, before anything reaches the customer. We built Verel Coordinator around that gate: it routes inbound work by your rules and holds customer-facing replies for a compliance check.
The economics: run the numbers yourself
The usual objection: if a person still has to check everything, why automate? The answer is that checking a draft takes far less time than writing it. Use your own volumes rather than our estimates. For each architecture, weekly cost is:
- ▸Manual: tasks × minutes per task × hourly rate ÷ 60, plus the cost of errors from tired staff
- ▸Fully autonomous: tasks × AI cost per task, plus tasks × agent error rate × average cost of one error
- ▸HITL: tasks × review minutes × hourly rate ÷ 60, plus tasks × AI cost per task, plus errors reviewers miss × cost per error
Two terms usually decide it. The first is how review time compares with doing the task by hand. For structured work like invoices, intake forms, and standard replies, review tends to take a small fraction of the manual time. Time it on a sample of real cases before you rely on that. The second is the cost of a single error. When one wrong payment or contract clause costs more than a month of review time, fully autonomous is the expensive choice. The per-task price does not change that.
Saved minutes only count when they turn into money or capacity. Apply the realisation factor to the review-time saving before you compare the three lines.
Don't chase 100% automation. Handling the standard cases takes weeks. Squeezing out the last edge cases takes months, and the result tends to be brittle. Put in an approval gate now and start capturing the savings on the standard cases.
The agent cost breakdown covers what the build costs.
Pausing for days without breaking anything
What matters to the business here is durability. A reviewer could answer in five minutes or after a long weekend. The workflow can't lose its place, hold a server open, or quietly drop the transaction while it waits.
A typical web request gives up after 30 to 60 seconds. If an approval step sits inside that request, it fails before the reviewer has even opened the notification. Demo builds hit this all the time. They hold the agent's progress in memory, so a server restart or a page refresh wipes it.
The fix is to save the agent's full working state to a database after every step. LangGraph calls this a checkpointer. At the approval point, the agent saves its state, sends a notification, and shuts down. It uses no compute while it waits. The reviewer's click triggers a webhook, which loads the saved state and picks up at exactly the point it stopped.
Here's the core of it in LangGraph, with state saved in Postgres. LangGraph's human-in-the-loop documentation describes interrupt() as pausing graph execution at a specific point and waiting for external input before continuing.
</>View technical implementation · عرض التفاصيل التقنية
from langgraph.types import interrupt, Command
from langgraph.checkpoint.postgres import PostgresSaver

def review(state):
    # Pauses here. The payload is what the reviewer UI displays.
    decision = interrupt({"draft": state["draft"], "sources": state["sources"]})
    if decision["action"] == "edit":
        return {"draft": decision["draft"], "approved": True}
    return {"approved": decision["action"] == "approve"}

with PostgresSaver.from_conn_string(DB_URI) as checkpointer:
    checkpointer.setup()  # first run only: creates the checkpoint tables
    graph = builder.compile(checkpointer=checkpointer)
    config = {"configurable": {"thread_id": "invoice-4821"}}

    graph.invoke({"invoice_id": "4821"}, config)  # runs until interrupt()

    # Later, in the webhook handler, possibly another process:
    graph.invoke(Command(resume={"action": "approve"}), config)
The thread_id connects the resume call to the right paused run. Whatever you pass to Command(resume=...) becomes the return value of interrupt().
One behavior surprises teams. On resume, LangGraph runs the paused step again from its first line. Any side effect placed before interrupt() in that step happens twice, whether that's an API call, an email, or a database write. Put side effects in a separate step after the review. Pattern 2 of our LangGraph production patterns covers this checkpointing setup in more depth.
What the reviewer sees decides whether this pays off
Being able to pause is pointless if review is slow. Say a reviewer has to reread a 20-page source document to check a two-line summary. Review now takes as long as doing the work by hand, and the savings disappear.
A good review screen shows three things at once:
- ▸The proposed action. Exactly what will happen, for example: "Send this email to this address."
- ▸The inputs. The data the agent used to decide.
- ▸The citations. The exact paragraph or record behind each claim, highlighted in the source.
Put the review where your team already works. If they live in Slack, the agent can post the draft, the source link, and Approve and Edit buttons. If you need audit trails or role-based access, build a dedicated review screen. Either way, the reviewer edits instead of writing from scratch.
Then there's the problem that undermines the whole design: automation bias. People who see the agent get it right a run of times start approving without reading. Make reviewers engage:
- ▸Required field checks. For risky values, the reviewer confirms each one before Approve becomes available. One example: "Discount is at or below the approved tier."
- ▸Seeded test items. Drop items with known errors into the queue and track who catches them. This measures attention directly.
- ▸Approval speed tracking. An approval that comes faster than anyone could read the draft is a signal. Flag it.
Plan for the reviewer who never answers. Set a time limit on each approval. When it runs out, the system sends the item to a backup reviewer or a manager. A paused workflow should never sit blocked indefinitely without anyone noticing. The approval gate is one of seven controls; the other six failure modes and their controls are in the hub post.
→ When an AI Agent Makes a Mistake: Failure Modes and the Controls That Contain Them → Why Prompt Guardrails Fail in Production, and What an Output Check Does Instead → AI Lead Routing in Regulated Firms: Who May Say What to a Prospect, Enforced by the SystemFrequently Asked Questions
Does a human in the loop slow the process down? In machine time, yes, because the system waits for a person. In business time, usually no. A draft ready in seconds and approved two hours later still beats a report someone writes three days from now. Measure the whole turnaround, not the model's response time.
Can we phase the human out over time? For some categories, yes, if the data supports it. Log every proposal next to what the reviewer actually approved. When one category shows a long run of approvals with no edits, move it to spot-checks. Keep gates on anything irreversible or customer-facing until the error cost justifies removing them. In the EU, Article 14 of Regulation (EU) 2024/1689, the AI Act, covers this. It requires high-risk AI systems to be designed so that natural persons can effectively oversee them while in use.
What happens if the agent is wrong and the reviewer approves it anyway? Responsibility for that error sits with your process, not the model. That's why the required field checks, seeded test items, and approval speed tracking above matter. Every approval should log who approved, when, and what they saw. Then a mistake can be traced and fixed.
This week: gate one action and time it
Pick one irreversible action your agent takes today: an email it sends, a record it writes, a payment it triggers. Put a gate in front of it, even a crude one that posts the draft to a channel and waits for a reply. Then time the review on 20 real cases. Those 20 numbers tell you whether the economics above hold for your work, before you spend anything on a review screen.