How to Add an AI Feature to Your SaaS Without Rebuilding the Product
If you put model calls inside your core application, one slow response can stall it for every user. A separate AI service fed by a queue keeps your product fast, keeps each customer's data apart, and lets you see the cost per action before launch.
The fastest way to break a working SaaS product is to call a language model from inside your main web application. A model response can take several seconds. During that time, a web server worker that should be loading dashboards sits idle. Add enough users and your login page slows down because of a feature most of them never touched.
You don't need a rebuild to fix this. Put the AI work in a separate service and connect it to your product through a queue. Your core application keeps doing what it already does well.
This post is for a product you already run. If you are starting from nothing, begin with the stack we recommend for a new AI product instead. Come back here when you have customers to protect.
Why model calls do not belong in your web server
A typical database query returns in tens of milliseconds. A model generation takes seconds, and a long answer can take much longer. The time depends on prompt length, output length and how busy the provider is.
Web frameworks such as Rails, Django and Express handle a limited number of requests at once. Each slow model call holds one of those slots open for its full duration. When many users click "Generate report" together, the slots run out. Users who only wanted to log in now wait behind them.
The second problem is failure. Model providers rate-limit you, time out and have outages. If the call sits inside a user's web request, that error goes straight to the user. Your team then adds bigger timeouts and retries to the main codebase. Within a few months you have prompts hardcoded across controllers and nobody wants to touch them.
The third problem is tooling. Most agent frameworks, evaluation libraries and vector database clients are built Python-first. Using them from a PHP or Ruby monolith means writing wrappers and maintaining them yourself.
If you had to raise a request timeout in your main application just so an AI feature could finish, the overload problem has already started.
The sidecar pattern: a separate service fed by a queue
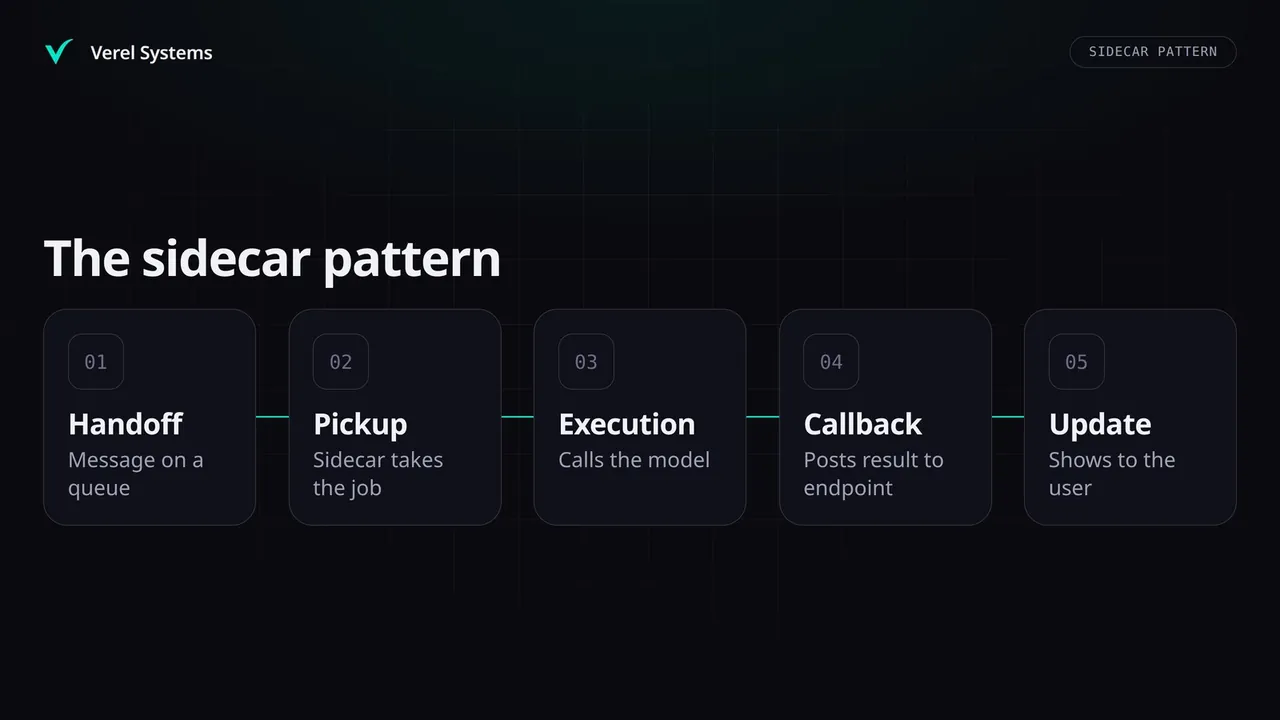
The fix is a standalone AI service that runs beside your product. Engineers call this a sidecar. Your core application still owns business logic, authentication and the system of record. The sidecar owns prompts, retrieval, model calls and everything else that is slow or unpredictable.
Here is the flow for a typical feature, such as "draft a reply to this support ticket":
- ▸Trigger. The user clicks the button. Your application records a job and returns a "working on it" state at once.
- ▸Handoff. The application puts a small message on a queue, such as Redis, RabbitMQ or AWS SQS. The message holds the ticket ID, the tenant ID and a job ID.
- ▸Pickup. The sidecar takes the job from the queue. It runs on infrastructure built for long tasks, separate from your web tier.
- ▸Execution. It fetches the context it needs, calls the model, uses any tools and handles its own retries if the provider rate-limits it.
- ▸Callback. It posts the result to an internal endpoint on your application, together with the job ID.
- ▸Update. Your application saves the result and shows it to the user through a WebSocket push or polling.
The business result is containment. If the sidecar crashes, slows down or loses its model provider, your main product keeps serving traffic. The feature degrades and the rest of the product does not.
Three details decide whether this holds up in production:
- ▸Idempotent jobs. Queues can deliver the same message more than once. Key every job by its ID so a retry never posts two replies.
- ▸A dead-letter queue. After a set number of failed attempts, move the job aside and mark it failed in your UI. Nothing should retry forever.
- ▸Per-tenant quotas at the sidecar. Rate limits and token budgets live in one place. One heavy account can't drain your margin or slow other customers.
Your existing engineers work with the sidecar the way they work with Stripe or Twilio: a defined request, a defined callback, documented error codes. They don't need to become experts in prompts or embeddings to keep shipping the core product.
Keeping each customer's data separate
Enterprise buyers will ask one question before anything else. How do you stop Customer A's data from showing up in Customer B's answers? You need an architectural answer to that, because a policy document alone won't satisfy them.
Two shortcuts cause most of the trouble. One is giving the AI direct SQL access to your production database. The other is loading a user's entire history into every prompt. The first is a security hole. The second is a cost problem that also tends to produce worse answers.
The safer design has two rules.
Scoped tokens, not database access. With each job, the sidecar receives a short-lived token limited to one tenant. When it needs data, it calls your application's internal API with that token. Your application stays the single source of truth and applies the access rules it already enforces. If the sidecar asks for something outside that tenant, the request is refused.
A hard tenant filter on every search. Some features search uploaded documents, which is retrieval-augmented generation, or RAG. For those, the sidecar keeps its own vector index in a store such as Qdrant or pgvector. Every stored chunk carries a tenant_id field. Every query is filtered by the active tenant_id before it runs. That filter comes from the job, never from the model or the user's text.
This gives you clear evidence for a security review. The AI service has no direct database credentials. It works only through scoped tokens, and its searches cannot return another organization's documents. That helps in a SOC 2 assessment. It also helps in a data-protection review under laws such as the UAE's Federal Decree-Law 45 of 2021 or the Saudi PDPL. Our PDPL checklist for AI systems lists what a reviewer will ask to see. The design doesn't make you compliant by itself. It does make the isolation answer short and checkable.
Choosing the integration pattern
How your application and the AI service talk to each other drives user experience, cost and risk. The table below is the decision most teams need to make first.
| Integration pattern | Typical wait for the user | Risk to the core product | Best used for |
|---|---|---|---|
| Synchronous call | <2 seconds | High | Classification, intent routing, short labels |
| Async queue + callback (sidecar) | Roughly 5 to 30 seconds | Low, isolated | Drafting replies, summaries, report generation |
| Long-running agent job | Minutes | Low, isolated | Multi-step research, document extraction, tool-using workflows |
Synchronous call. Use this only with small, fast models or specialized classifiers, for tasks that reliably finish in under two seconds. Deciding which queue a message belongs in is a good example. Do not use it for generation.
Async queue and callback. This is the right default for most SaaS AI features. Users see a loader or progress state. You can then use larger models from the Claude, GPT or Gemini families without slow responses holding up your web servers. If users want to watch text appear, stream from the sidecar to the browser. Your web servers stay out of that path.
Long-running agent job. This is for features where the AI uses tools, checks its own work, or runs several steps. The user starts the job and gets a notification when it finishes. The sidecar needs its own state store, usually PostgreSQL, so a job can resume after a restart instead of starting over.
Costing the feature before you build it
Work out the cost per action before you commit engineering time. Running costs come in two parts. Inference is what the model provider charges per token. Compute is the infrastructure that runs the sidecar.
The formula for inference is simple.
</>View technical implementation · عرض التفاصيل التقنية
Monthly inference cost = users × actions per user per day × 30
                         × (input tokens × input price + output tokens × output price) ÷ 1,000,000
Prices here are quoted per million tokens. Here is a worked example, and every number in it is illustrative. The rates sit in the range of the small, fast tiers listed on OpenAI's and Anthropic's price pages when this was written. Check the current sheet before you budget, because these change often.
- ▸Illustrative rates: $0.15 per million input tokens, $0.60 per million output tokens.
- ▸1,000 active users, each using the feature 5 times a day: 5,000 actions daily.
- ▸Each action sends about 3,000 input tokens (ticket plus history) and returns about 500 output tokens.
The math:
- ▸Input: 5,000 × 3,000 = 15,000,000 tokens a day. 15 × $0.15 = $2.25 a day.
- ▸Output: 5,000 × 500 = 2,500,000 tokens a day. 2.5 × $0.60 = $1.50 a day.
- ▸Inference total: $3.75 a day, about $112.50 a month. That works out to $0.00075 per action.
For compute, assume $40 to $100 a month at this volume on serverless platforms that bill per second, such as Modal or Railway. Treat that as an estimate and confirm it against your own traffic pattern. Total running cost lands at roughly $150 to $215 a month for 5,000 actions a day.
Two things change this number more than the model choice does. First, context size: doubling the history you send roughly doubles the input line. Second, retries and runaway loops, which can multiply the bill without any user noticing. Both are covered in our post on retries, context growth and evaluation overhead. Per-tenant budgets at the sidecar are your control for both.
Then compare cost to revenue in your own terms. The feature may support a price increase of X per user, or cut churn by Y accounts a month. Put those figures next to the monthly cost above. If the ratio is unconvincing on paper, it won't improve after launch. When it does convince you, the next job is to turn cost per action into a plan price, which has its own post.
Frequently Asked Questions
How long does it take to add a sidecar to an existing product? For a single, well-defined feature, plan for weeks rather than months. Most of the effort goes into agreeing the contract between your application and the sidecar. The rest goes into tuning retrieval and prompts until accuracy meets your bar. The infrastructure is usually the smaller part.
What happens when the model provider has an outage? Your core product keeps running. Failed jobs go back on the queue with increasing delays between attempts. After a set limit, they move to a dead-letter queue and show as failed in your UI. You can also configure the sidecar to fail over to a second provider, for example from a GPT model to a Claude model.
How do we stop the AI from inventing data it does not have?
Limit what it can see and give it a way to refuse. The sidecar answers only from the payload and from data fetched through the scoped API. When required context is missing, it returns a defined code such as INSUFFICIENT_CONTEXT instead of guessing. Your application catches that code and asks the user for what is missing. Test this before launch with cases where the answer is deliberately absent.
Your next step is a cost sheet. Write down your user count, actions per user, tokens per action and your provider's current rates, then run the formula above. If the per-action cost leaves you a margin, build the sidecar. If it doesn't, work on context size and pricing before you work on the model.