RAG for Law Firms: Bates-Level Citations, Ethical Walls, and When On-Prem Is Worth It
A legal RAG system earns its keep only when every answer points to a Bates number an attorney can check and respects the ethical walls already in your DMS. Here is how to build both, and how to decide where the model should run.
An answer an attorney cannot verify saves no time. Say the system reports that a contract allows termination on change of control. Someone still has to find the clause. If there is no pinpoint citation, they read the whole agreement anyway. The software bill goes up and the review hours stay where they were.
That is the test for legal RAG. RAG stands for retrieval-augmented generation. The system searches your documents first, then writes an answer using only what it found. In a law firm, getting it right comes down to three engineering decisions:
- ▸How documents are split and labelled.
- ▸How access rules carry over from your document management system.
- ▸Where the model runs.
Many firm pilots skip all three. That is why they look good on ten clean PDFs and fall apart on a real production set.
Citations start at ingestion, not in the prompt
Basic RAG implementations often still default to splitting every document into fixed blocks of about a thousand tokens. A token is a word fragment. Fixed splitting throws away the structure legal work depends on: Bates numbers, page breaks, section numbering, footnotes, exhibit boundaries. Once a chunk spans the end of Section 4.2(a) and the start of 4.3, no prompt can recover which section a sentence came from.
The fix is structural chunking. Before anything is indexed, the parser identifies the document's structure and splits along it. Every chunk then carries its own metadata:
- ▸Bates number or range
- ▸Source file and DMS document ID
- ▸Page number
- ▸Section or paragraph heading
- ▸Matter number and client
- ▸Document type and date (contract, deposition, email, exhibit)
Bates numbers as a first-class field: For Bates-stamped productions, the pipeline must extract the stamp as its own metadata field before chunking. The index stores it with the text, so the answer reads "Source: DEF-001452" instead of "Document 4, page 12." Validate stamps against the expected prefix and sequence. OCR misreads them (an "O" for a "0") often enough that gaps and malformed numbers should be flagged at ingestion, not discovered in a deposition.
Search has to handle exact strings as well as meaning. Attorneys type Bates numbers, party names and defined terms literally. Vector search, which matches by meaning, is weak at exact identifiers. Hybrid search runs a keyword match and a meaning match together and merges the results. For legal corpora, hybrid is the right default.
Generation is the last step, and the model must attach a citation to every claim. Instead of:
The defendant was present at the facility on October 14th.
the system produces:
The defendant was present at the facility on October 14th [DEF-001452, ¶3].
An instruction in the prompt is not enough. Models drop or invent citations under pressure, which is why prompt guardrails often fail in production. A separate check runs after generation and confirms three things:
- ▸Every sentence carries a citation.
- ▸Every cited Bates number was actually among the retrieved chunks.
- ▸The supporting text appears in that chunk.
Anything that fails is removed and flagged, or the whole answer is blocked. "This is not in the documents provided" is a valid answer. A system without that constraint may fill the gap from its training data. That is how hallucinated case law reaches a filing. Stanford HAI reported in May 2024 that leading AI legal research tools hallucinated between 17% and 33% of the time.
Ethical walls belong in the database query
A firm's DMS, whether iManage, NetDocuments or SharePoint, enforces who can see which matter. An associate in real estate should not be able to search an unannounced merger in the corporate group. Export everything into a single unfiltered index and you risk bypassing the ethical walls the firm maintains. Without access controls, the system may summarize restricted documents for anyone who asks the right question. NetDocuments describes Workspace Security Manager policies that lock user and group permissions on a workspace to create walls.
The control works like this. At ingestion, the pipeline reads each document's access control list from the DMS and stores it as metadata on every chunk. In schema terms, that is allowed_groups copied from the source system onto every chunk, with deny by default. When a user submits a query, the backend identifies them through the firm's directory, such as Active Directory or Entra ID. It then applies a hard filter: search only chunks where this user or one of their groups is permitted.
The filter runs inside the database, before retrieval. Restricted text never reaches the model. You cannot ask the model to decide who may see what, because the model should never hold that text in the first place.
Two details separate a working wall from a demo:
- ▸Permission changes propagate. A lateral hire triggers a new wall. Your index has to pick that up on the same schedule as the DMS, not at the next full reindex.
- ▸The wall is tested before launch. Run a set of queries as a walled user and require zero restricted chunks in the results. Treat it as a pass/fail gate, alongside accuracy.
Where the model runs: a confidentiality decision, not a cost decision
The privilege question is often overstated. Sending documents to an enterprise API with zero-retention, no-training terms does not by itself waive privilege. Firms already rely on cloud DMS and e-discovery platforms on the same reasoning. The ABA's Formal Opinion 512, issued in 2024, treats generative AI under existing duties of competence and confidentiality. It does not create a ban on cloud tools. AWS states that Amazon Bedrock never shares customer data with model providers or uses it to train models.
What usually decides the matter is contractual. Client outside counsel guidelines often restrict where data may go and which vendors may process it. Some regulated and government clients prohibit third-party processing outright. For those matters, the answer is settled before anyone looks at cost. Firms in the Gulf face their own data residency rules under local law. Those need a separate analysis, not a borrowed US ethics opinion.
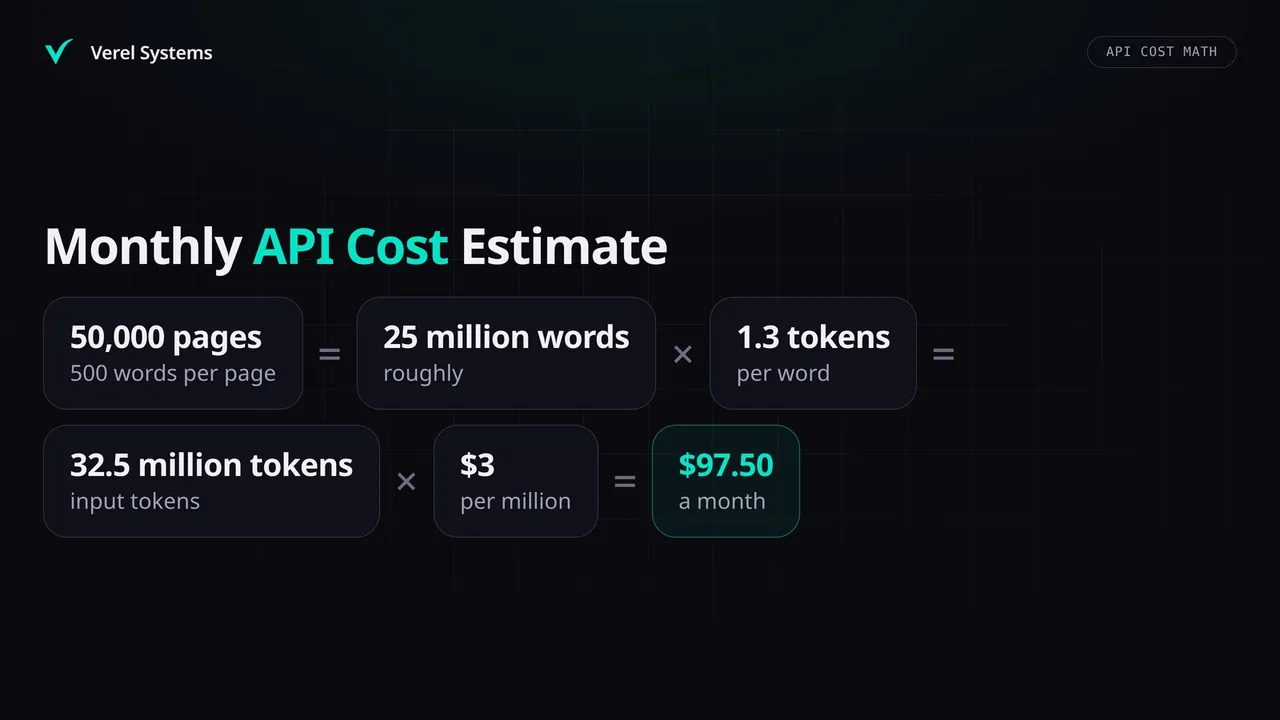
Do not build on-prem expecting to save on API bills. Here is a worked example with labelled assumptions:
- ▸50,000 pages a month, at roughly 500 words per page, is about 25 million words.
- ▸At roughly 1.3 tokens per word, that is about 32.5 million tokens.
- ▸At an assumed $3 per million input tokens, that comes to about $97.50 a month.
A server that runs a capable open-weight model needs roughly 80 to 96GB of GPU memory. That follows from the rule in our on-prem guide: weight memory is parameters times bytes per parameter. A 70 billion parameter model at 8-bit is about 70GB of weights before working memory; at 4-bit, roughly 35 to 40GB. Typically that means two 48GB workstation GPUs or one 96GB card. Get a vendor quote for that hardware and set it against $97.50 a month. The payback runs to years. You buy it because a client's terms require the documents to stay on your hardware, or because your risk policy does.
| Architecture | Where documents go | What you are trusting | Cost shape | Right fit |
|---|---|---|---|---|
| Enterprise API, zero-retention | Provider's servers, processed and deleted | Provider's contract terms and security | Per token; scales with volume | Matters without client restrictions on third-party processing |
| Private cloud tenant | The firm's own cloud account, model hosted there | Cloud provider's infrastructure; firm controls the tenant | Fixed compute hours | Firms already approved for cloud by their clients |
| On-premise | Hardware the firm owns, in its own facility | The firm's own IT and physical security | Upfront hardware plus maintenance | Matters whose guidelines forbid third-party processing |
Many firms end up with more than one. The routing rule is by matter, read from the same metadata that drives the ethical walls. Whether the on-prem option pays at your volume is a question the breakeven math for local inference answers; for most firms it is a confidentiality purchase, not a saving.
Frequently Asked Questions
What hardware does on-premise legal RAG actually need? A capable open-weight model of around 70 billion parameters needs roughly 80 to 96GB of GPU memory for responsive interactive use. That is usually two 48GB workstation GPUs or one 96GB card. Smaller models run on far less and handle extraction tasks well. Test on your own documents before sizing hardware for the largest model.
How do we know the answers are accurate before attorneys rely on them? Build a test set from real questions on a closed matter, with known correct answers and Bates citations. Measure two things. First, did retrieval find the right passage? Second, is every claim in the answer supported by that passage? Set pass thresholds before launch, add the walled-user access test, and rerun everything whenever documents, models or prompts change.
Can it draft briefs or legal arguments? It should not. RAG is built for retrieval and extraction: building timelines from discovery, comparing a contract against your playbook, finding every indemnity clause across a data room. It does not do original legal reasoning. Keep it on tasks where every output can be checked against a cited source.
The first thing to check in any pilot you already run is simple. Ask it for a fact from a closed matter and see whether the answer cites a Bates number you can open. Then log in as a walled user and try to retrieve that matter. If either test fails, fix it before anything else. If you want those two tests run against your setup, our AI Audit costs $2,500 fixed. Book the free architecture call to scope it.
→ A Metadata Schema for Enterprise RAG: Dates, Access Control, Status and Lineage → When On-Premise AI Pays Off in the UAE and Saudi Arabia: Breakeven Math → Why Prompt Guardrails Fail in Production, and What an Output Check Does Instead