Agent Evals in Production: Tracing Tool Use and Trajectories
Grading only an agent's final answer misses most of what goes wrong. Step-level tracing, targeted judge prompts and a CI gate catch tool-use errors before they reach customers. Here is the worked trace, the judge prompts, and what it costs.
The agent answered politely, used good grammar and was wrong. A customer reported a duplicate charge from "last Tuesday." The agent searched the right system with the wrong year. It got back nothing and said no duplicate existed. If you grade only the final message, that run passes.
The damage usually happens between the question and the answer. An agent picks a tool, writes the inputs for it, reads what comes back and decides what to do next. Any of those steps can fail quietly. The answer at the end often looks fine anyway.
This is why evaluation methods built for question-answering systems fall short once an agent starts taking actions. It is also one of the more common reasons agent projects stall between demo and production. The demo used ten friendly test questions. Production is thousands of runs a day, and nobody can see inside them. Many of those runs fail at the API layer without raising a single error.
Step errors multiply
Here is the math that should shape your evaluation budget. If each step in a workflow succeeds with probability p, a workflow of n steps succeeds with probability p to the power n.
Take a five-step refund workflow: classify the request, fetch the customer record, check the refund policy, issue the refund, send a confirmation. Say each step is right 95% of the time. That feels excellent in a pilot.
</>View technical implementation · عرض التفاصيل التقنية
Step 1  Classify request      0.95   cumulative 95.0%
Step 2  Fetch CRM record      0.95   cumulative 90.3%
Step 3  Check refund policy   0.95   cumulative 85.7%
Step 4  Issue refund          0.95   cumulative 81.5%
Step 5  Send confirmation     0.95   cumulative 77.4%
Roughly one run in four goes wrong somewhere. Add an approval step and a logging step, and seven steps at 95% each puts you just under 70%.
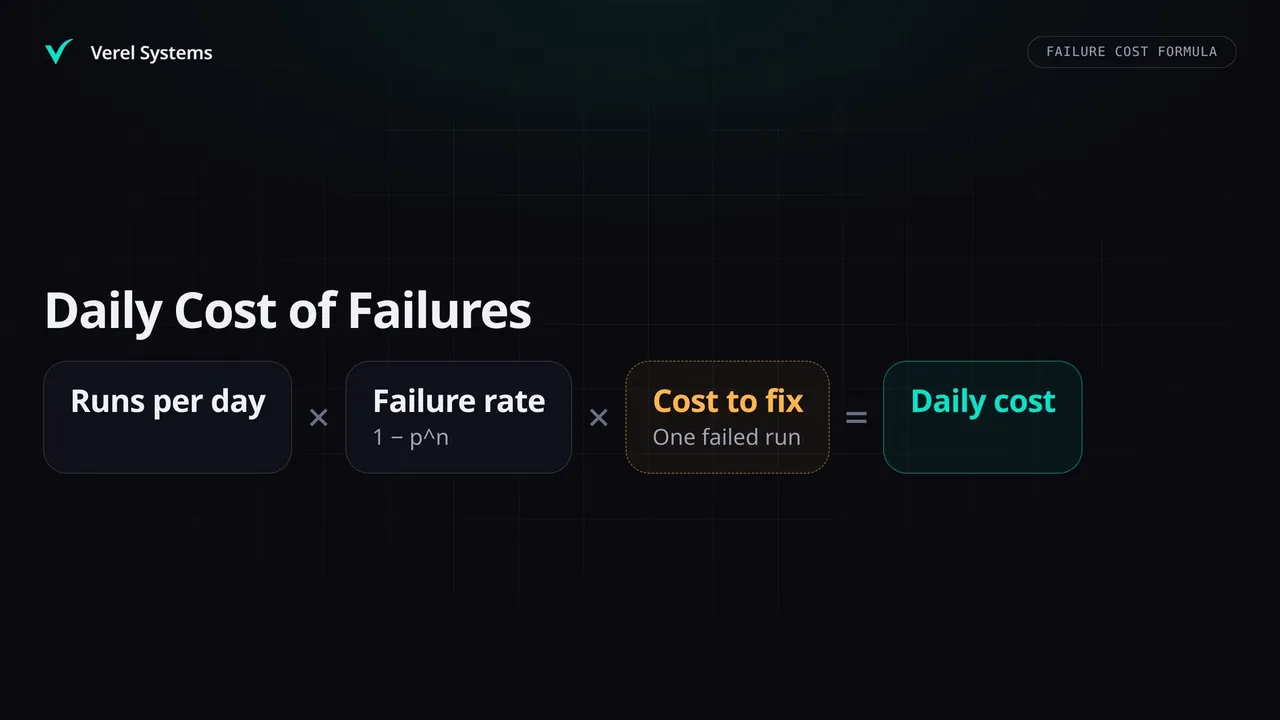
You can work out what this costs with your own numbers:
Daily cost of failures = runs per day × (1 − p^n) × cost to fix one failed run
The last term is the one most teams underestimate. It covers staff time on the escalation, any refund issued twice, and the customer who leaves. Fill in your own figures. For most workflows, the result is larger than the whole AI budget.
There are two ways to improve the outcome: make each step more reliable, or use fewer steps. You can only do either if you can see which step is failing. That is the whole job of trajectory evaluation.
Why final-answer metrics miss it
A trajectory is the full, ordered record of one run. It holds every model call, every tool call with its exact inputs, every tool response and every decision in between. Standard metrics for question-answering systems assume a simple flow: question in, documents retrieved, answer out. The faithfulness and relevance scores in frameworks like RAGAS are examples. Agents loop, retry and change their own course.
Final-answer grading misses three kinds of failure.
Silent tool errors. The tool call technically succeeds and returns no error, but the inputs were wrong. A query for Q3 contracts with Q2 dates returns Q2 contracts. The agent then summarises the wrong documents with full confidence.
Faithful to the wrong source. Someone asks for last quarter's revenue. The agent calls web search when it should have called the internal finance database, finds nothing, and replies that it has no access. A faithfulness metric scores that answer perfectly, because it matches what was retrieved. The real failure was the choice of tool. Worse, the query may have gone to a public search engine.
Right answer, wrong path. An agent reports that shipment 8842 is two days late. That is correct. But the trace shows it never called the live tracking system. It pieced the answer together from an old wiki page. Next week the same path will be wrong, and your tests will not have warned you.
A worked example: one trace, one judge
You need two things here. The first is tracing: every step gets logged as its own record, with inputs and outputs, using a tool such as Langfuse or Weave. The second is a set of narrow checks that run over those records. Below is a simplified, illustrative trace of the duplicate-charge run from the opening. It uses the field layout most tracing tools capture.
</>View technical implementation · عرض التفاصيل التقنية
trace_id: tr_8f21  run_date: 2026-10-16  workflow: billing_dispute

span 1  llm.classify
  input:  "I was charged twice last Tuesday, card ending 4417"
  output: {"intent": "duplicate_charge", "confidence": 0.93}

span 2  tool.get_transactions
  args:   {"customer_id": "C-20931",
           "start_date": "2025-10-13",
           "end_date":   "2025-10-13"}
  status: 200   latency_ms: 212
  result: []

span 3  llm.decide
  output: "No transactions found. No duplicate charge exists."

span 4  llm.reply
  output: "I've checked your account and found no duplicate
           charge on that date. Is there anything else?"
Every span returned success. The reply is polite and fits the empty result it got. A final-answer grader passes it. The actual mistake is in span 2: the year is off by one.
Two checks catch it, and they work in sequence.
Deterministic check first. Plain code, no AI. If a tool call uses a date argument and returns an empty result, and that date is more than 30 days from the run date, flag the span. This is cheap, instant and needs no judgment.
Then a targeted judge. The judge is a second model that grades one step against one question. It does not grade the whole conversation. The prompt looks like this:
</>View technical implementation · عرض التفاصيل التقنية
You are checking one tool call. Do not judge the final reply.

User message: {user_message}
Run date: {run_date}
Tool call: {tool_name}({tool_args})

Question: Are the date arguments consistent with the dates the
user referred to, relative to the run date?

Respond in JSON:
{"verdict": "PASS" | "FAIL", "expected": "...", "reason": "<one sentence>"}
On this trace the judge returns:
</>View technical implementation · عرض التفاصيل التقنية
{"verdict": "FAIL",
 "expected": "start_date 2026-10-13, end_date 2026-10-13",
 "reason": "User said 'last Tuesday' on 2026-10-16; arguments use 2025."}
The fix is now obvious and small. Work out relative dates in code before the agent ever sees them, and pass in the absolute date. Without the trace, the same bug shows up as a slow rise in "agent couldn't find my transaction" complaints. Someone then spends days going through logs.
The judge prompts that do the most work each target one failure:
- ▸Tool selection: "Given the request and these available tools, was this the right tool? PASS or FAIL, with one sentence."
- ▸Parameter grounding: "Is every argument either taken from the user's message, from an earlier tool result, or from a stated default?" This catches invented IDs and invented dates.
- ▸Result interpretation: "Does the agent's next step follow from what the tool returned?" This catches an agent reading an empty result as a confirmed "no."
- ▸Loop termination: "Did the agent stop once it had enough information, or make a repeat call?"
Narrow questions get answers you can rely on. "Was this run good?" gets you a judge in a good mood.
Retry loops are where cost runs away
One failure deserves its own control. An agent sends a malformed request, gets an error, and tries again. Most setups add the failed attempt to the agent's working memory, so the model knows what it has tried. That makes each retry larger than the last.
Each retry resends the whole context plus every earlier error, so input tokens grow faster than the retry count. One stuck run can cost as much as hundreds of normal ones, and what retries do to an API bill has the arithmetic.
The control is not a smarter prompt. It is a hard cap on retries per tool. A repeated identical error also ends the run and hands it to a person. Your traces then tell you which tool keeps triggering the cap. For how to design those handoffs, see our LangGraph production patterns.
Gate changes in CI, sample production nightly
Evaluation runs in two places. You need both.
Before release: a CI gate. CI (continuous integration) runs automated tests every time someone proposes a change. Any change to a prompt, a model, a tool description or the graph should trigger it. It runs against a golden dataset: 100 to 500 real inputs, each paired with the tools that should be called and what counts as success. Include edge cases, hostile inputs and the multi-step requests that broke things before. The approach mirrors the 100-question test set we use for RAG, with expected tool calls in place of expected citations.
The gate compares the change against the current production version, step by step. A fix for invoice handling that drops contract classification by four points does not get merged. Without this gate, you find that regression when a customer complains. It also changes how your team works: engineers stop being afraid to touch prompts.
After release: sampled production evaluation. Do not grade every run. Grade a random sample to track overall health, and add every run that matches a risk filter: any tool error, any run over your time limit, any run that hit a retry cap, any empty tool result. Risk-filtered runs are where most of your useful findings come from.
| Where | What runs | What it catches | What happens on failure |
|---|---|---|---|
| CI, on every change | Golden dataset, deterministic checks, step judges, compared against baseline | Regressions from prompt, model or tool changes | Merge blocked |
| Production, every run | Schema validation, retry caps, deterministic flags | Malformed calls, runaway loops | Run stopped or handed to a person |
| Production, nightly sample | Step judges on random sample plus risk-filtered runs | Silent tool errors, wrong tool choice, drift | Ticket opened, run added to golden dataset |
The last column of the bottom row is what makes this system improve over time. Every real failure caught in production becomes a permanent test case in CI.
What evaluation costs
Leaders often hesitate at the idea of using AI to check AI. The math is reassuring once you write it down.
Daily judge tokens = runs per day × sample rate × steps judged per run × tokens per judgment
Say you run 10,000 workflows a day, sample 10%, judge 4 steps per run, and each judgment uses about 500 tokens. That is 2 million judge tokens a day. Multiply by your judge model's price per million tokens. Small, fast models from the major families are fine for checks this narrow. At their typical prices, the daily total usually lands somewhere between cents and a few dollars.
The bigger costs are elsewhere. Building the golden dataset takes real staff time. Storing traces costs money at volume. Someone has to review flagged runs every week. Budget for that review time. Without it, the dashboard is decoration.
For the judge, use a different model family from the one running the agent. Models tend to approve reasoning that resembles their own, which Zheng et al. call self-enhancement bias. A separate, narrowly prompted judge gives you a more independent check. Every few weeks, spot-check a sample of judge verdicts by hand. A judge that has drifted is worse than no judge at all.
What tracing usually shows you to fix
Teams that start tracing tend to find the same thing first. The agent has too many choices. Give a model twenty tools and the instruction "use your judgment," and it will confuse tools with similar names and invent inputs.
The structural fix is to route first and then limit the tools. Classify the request up front. Send a refund request into a refund sub-workflow that can only reach the two or three tools refunds need. Fewer steps raise p to the power n directly. Fewer tools cut the number of wrong choices available. How much this saves depends on how far your current agent wanders, and your traces will tell you that exact number. Your agents may handle inbound requests that need rules about who may answer and what may be sent to customers. Verel Coordinator is built for that routing layer.
Limits on what an agent can do also make evaluation more reliable. When an agent has a small, defined set of options, each step's correct answer is clear and the judge's job is easier. Prompt-level instructions alone will not hold these limits under real traffic.
→ Evaluating a RAG System Before Launch: A 100-Question Test Set and Four Gating Metrics → When an AI Agent Makes a Mistake: Failure Modes and the Controls That Contain Them → Why AI Agents Fail at the API Layer: Seven Silent Failures and the Control for EachFrequently Asked Questions
Does tracing or judging slow down the user's response? No, if it is set up correctly. Tracing tools send their records in the background, separate from the reply. Judges run afterwards on stored traces, so the user never waits on them. The only checks that run inline are fast code checks, such as validating a tool's inputs and enforcing retry caps.
What should we do when a judge fails a step but the final answer was correct? Treat it as a real finding. It usually means the agent recovered by luck or after wasted retries. Both cost money, and luck runs out on slightly different inputs. Fix the tool description or the input handling, then add that run to your golden dataset.
Why not just write unit tests for our tools? Write them, because they confirm a tool works when it gets correct inputs. They cannot tell you whether the agent picks the right tool, or produces correct inputs from a messy customer message. Trajectory evaluation tests the agent's decisions. Unit tests check the code underneath.
This week: start with the CI gate
If you have neither trajectory evals nor a golden dataset today, start with the CI gate on a 100-case golden dataset. Pull 100 real requests from last month's logs, including the ones that went wrong. For each, write down the tool that should have been called and with what arguments. Run the current agent against them and count the misses. That number is your baseline, and every prompt change from now on has to beat it.