Speech-to-Speech or Cascade? Choosing a Voice AI Architecture Call Type by Call Type
Speech-to-speech models answer faster and hear tone. Cascades are cheaper, easier to audit and safer to check. Here is how to pick per call type, with a break-even formula.
You no longer have to wonder whether voice AI works. The decision now is which kind to build. That choice sets your cost per call, your audit trail, and how the system handles tone.
There are two designs on the market. A cascaded pipeline chains three systems. One turns speech into text, a language model writes the reply, and a third turns the reply back into speech. A native speech-to-speech model takes audio in and sends audio out, with no text step in between. Model families like GPT and Gemini now offer real-time audio modes of this kind. Both are described in the OpenAI Realtime API documentation and the Gemini Live API documentation.
Neither is the better technology in general. Each one is the better choice for a particular type of call.
Why latency is the first thing callers notice
Conversation research found a typical gap between speakers of around 200 milliseconds. The pattern holds across languages (Stivers et al., PNAS, 2009). Callers have no stopwatch, but they feel it. Once the pause runs much past half a second, people start talking over the agent, repeating themselves, or asking for a human.
A cascaded pipeline has more steps that each add delay. First the system has to decide that the caller has finished speaking. This is called endpointing. Set it too tight and it cuts people off. Set it too loose and every turn starts with dead air. Then come transcription, the model's first words, speech synthesis, and the network trip back to the phone line.
A well-engineered cascade can still respond in under 500 milliseconds. We cover how in our latency guide. But the work takes effort, and interruptions remain the weak spot. If a caller cuts in with "wait, my address changed," a cascade has to notice, stop the speech output, and re-plan. Done badly, the agent keeps talking over the caller. Barge-in and the memory problem it creates is its own failure mode.
Native models remove the two text handoffs. They tend to respond faster and recover from interruptions more naturally. The gap is real, but it is smaller than vendor demos suggest once your network and backend are in the path.
What text loses: tone
Picture a patient saying "great" in a flat voice after hearing the next free slot is three weeks out. Most transcription systems output only the word "great". If nothing else in the pipeline tracks tone, the language model may treat it as agreement and reply cheerfully.
Native models work on the audio itself, so pitch, pace and hesitation reach the model directly. That can help with de-escalation: the agent slows down, softens its reply, or offers a human sooner. On calls where frustration drives escalations, this matters. On a call that only confirms a delivery window, it hardly matters at all.
In regulated settings such as healthcare and finance, set up a separate transcript for every native-model call. Record the audio stream and send it to a transcription service in parallel, then write the text to your CRM after the call. An audio-to-audio conversation does not leave a searchable text record by default, and your compliance team will need one.
What text gives you: control
This trade-off rarely appears in vendor comparisons. In a cascade, the reply exists as text before anyone hears it. Your system can check that text first: block a promise of a refund, a medical claim, or a figure the agent should not quote. Prompt instructions alone do not hold up under real traffic, as why prompt instructions alone do not hold under real traffic explains. A check on the output does.
With a native model, the audio is produced directly. Some services stream a text version alongside the audio, but it arrives at the same moment, so any check runs in parallel, not beforehand. By the time a violation is flagged, the caller has often heard it.
If your calls carry regulated statements, that alone can settle the choice.
Cost: run the formula with your own quotes
Native audio is priced per audio token or per minute. On the OpenAI and Gemini pricing pages, it costs more per minute than a cascade of separate transcription, text and speech providers, once you convert tokens to minutes. Prices change often, so get current quotes for your own volume rather than trusting any blog table, ours included.
The useful question is not which costs less. It is whether the native premium pays for itself. Use your own numbers.
- ▸P = native cost per minute minus cascaded cost per minute
- ▸L = average call length in minutes
- ▸H = fully loaded cost of one human handoff
- ▸Premium per call = P × L
- ▸Break-even = native must prevent one handoff every H ÷ (P × L) calls
Suppose the premium per call is one-tenth of your handoff cost. Then native pays for itself if it prevents one escalation in every ten calls. Keep the units consistent. Handoffs are counted per call, never per minute of talk time.
Measure this before you commit. Run both designs on a slice of real traffic and compare escalation rates. Do not rely on a vendor's demo or a pilot staffed by your most patient testers.
Decision table
| Factor | Cascaded (speech-to-text, model, text-to-speech) | Native speech-to-speech |
|---|---|---|
| Response speed | Under 500ms is achievable, but it takes engineering | Typically faster; network and tool calls still add delay |
| Interruptions | Weaker; depends on endpointing tuning | Recovers more naturally |
| Tone and emotion | Lost unless you add a separate tone layer | Reaches the model directly |
| Checking replies before they are spoken | Yes, the text exists first | Usually only in parallel, after the fact |
| Audit transcript | Produced as part of the pipeline | Must be built as a separate process |
| Gulf Arabic dialects | Can use dialect-tuned transcription and Arabic voices | Usually weaker today; test on real calls |
| Cost per minute | Generally lower | Generally higher; check current pricing |
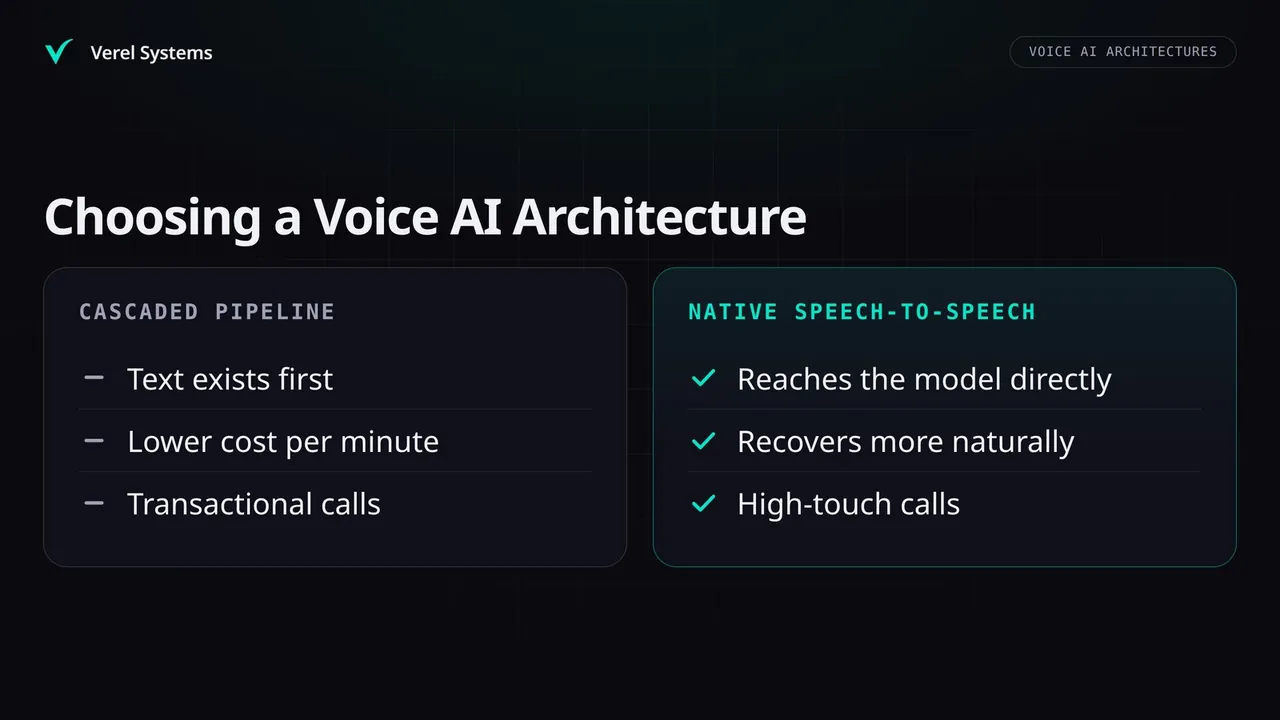
| Best fit | High-volume, transactional calls | High-touch calls where tone drives the outcome |
The split that works
Use a cascade for transactional calls. Appointment confirmations, order status, basic lead qualification and dispatch follow a linear question-and-answer pattern. Tone rarely changes the outcome. The lower cost per minute and the ability to check replies first add up at volume.
Use native for high-touch calls. Support triage, sensitive collections conversations and premium concierge lines are where frustration, interruptions and pacing decide whether the caller stays. There, the premium can be worth paying. Check it with the formula above.
Many operations need both. A short classification step at the start of the call can send each caller to the right design. That is more engineering than one system, so build it only when your call mix is clearly split.
Whichever you choose, the backend often matters more than the model. If an appointment or inventory lookup takes most of a second to return, the caller hears silence. A fast voice model does not fix that. Skipping this check means paying for low-latency audio and still delivering lag.
Frequently Asked Questions
Do native speech-to-speech models handle Gulf Arabic better than cascaded systems? Usually not today. Native models are trained mostly on English and widely spoken language varieties. They tend to be weaker on Gulf dialects and on code-switching between Arabic and English. A cascade lets you choose the transcription service that does best on your dialect and an Arabic voice that sounds natural. See choosing the transcription engine that does best on your dialect. Test any native model on recordings of your own callers before you commit.
Can we start with a cascade and switch to native later? Yes, but plan for real rework. A cascade manages the conversation and tool calls as text. Native models mix tool calls into a live audio stream. Your backend then has to handle lookups without blocking the audio. Keep your business logic and tool layer separate from the voice layer from the start, and the switch becomes a contained change.
What causes the most delay, regardless of the model? Distance and slow lookups. Say the model runs in the US, the database in Europe and the caller is in Dubai. Each round trip adds delay no model can remove. Host the inference servers, the databases the agent calls, and your phone or WebRTC gateway in the same region.
Run both designs on 100 calls of one call type, log escalation rate and p95 response time for each, and plug the difference into the break-even formula.
→ Voice AI Latency: How to Build a Streaming Pipeline That Answers in Under 500ms → Voice AI Failure Modes in Production: Latency, Barge-In, Dead Air and Code-Switching → Why Prompt Guardrails Fail in Production, and What an Output Check Does Instead